ChatArchive
A FastAPI and React app that imports conversations from four AI services into PostgreSQL so they can be searched, tagged, and organized in one place.
Problem
Chat exports from different AI services arrive in different shapes. Keeping the files is easy; finding a useful exchange later, seeing its surrounding messages, and grouping related conversations across services is harder. ChatArchive brings those exports into one searchable conversation library.
Approach
The FastAPI backend has separate import endpoints and parsers for ChatGPT, Claude, Gemini, and GitHub Copilot. Each parser handles its provider’s export format before the app stores conversations and ordered messages in a shared SQLAlchemy model. The model also tracks source IDs, import history, tags, and projects, so the React and TypeScript interface can browse and filter conversations without knowing each provider’s file format.
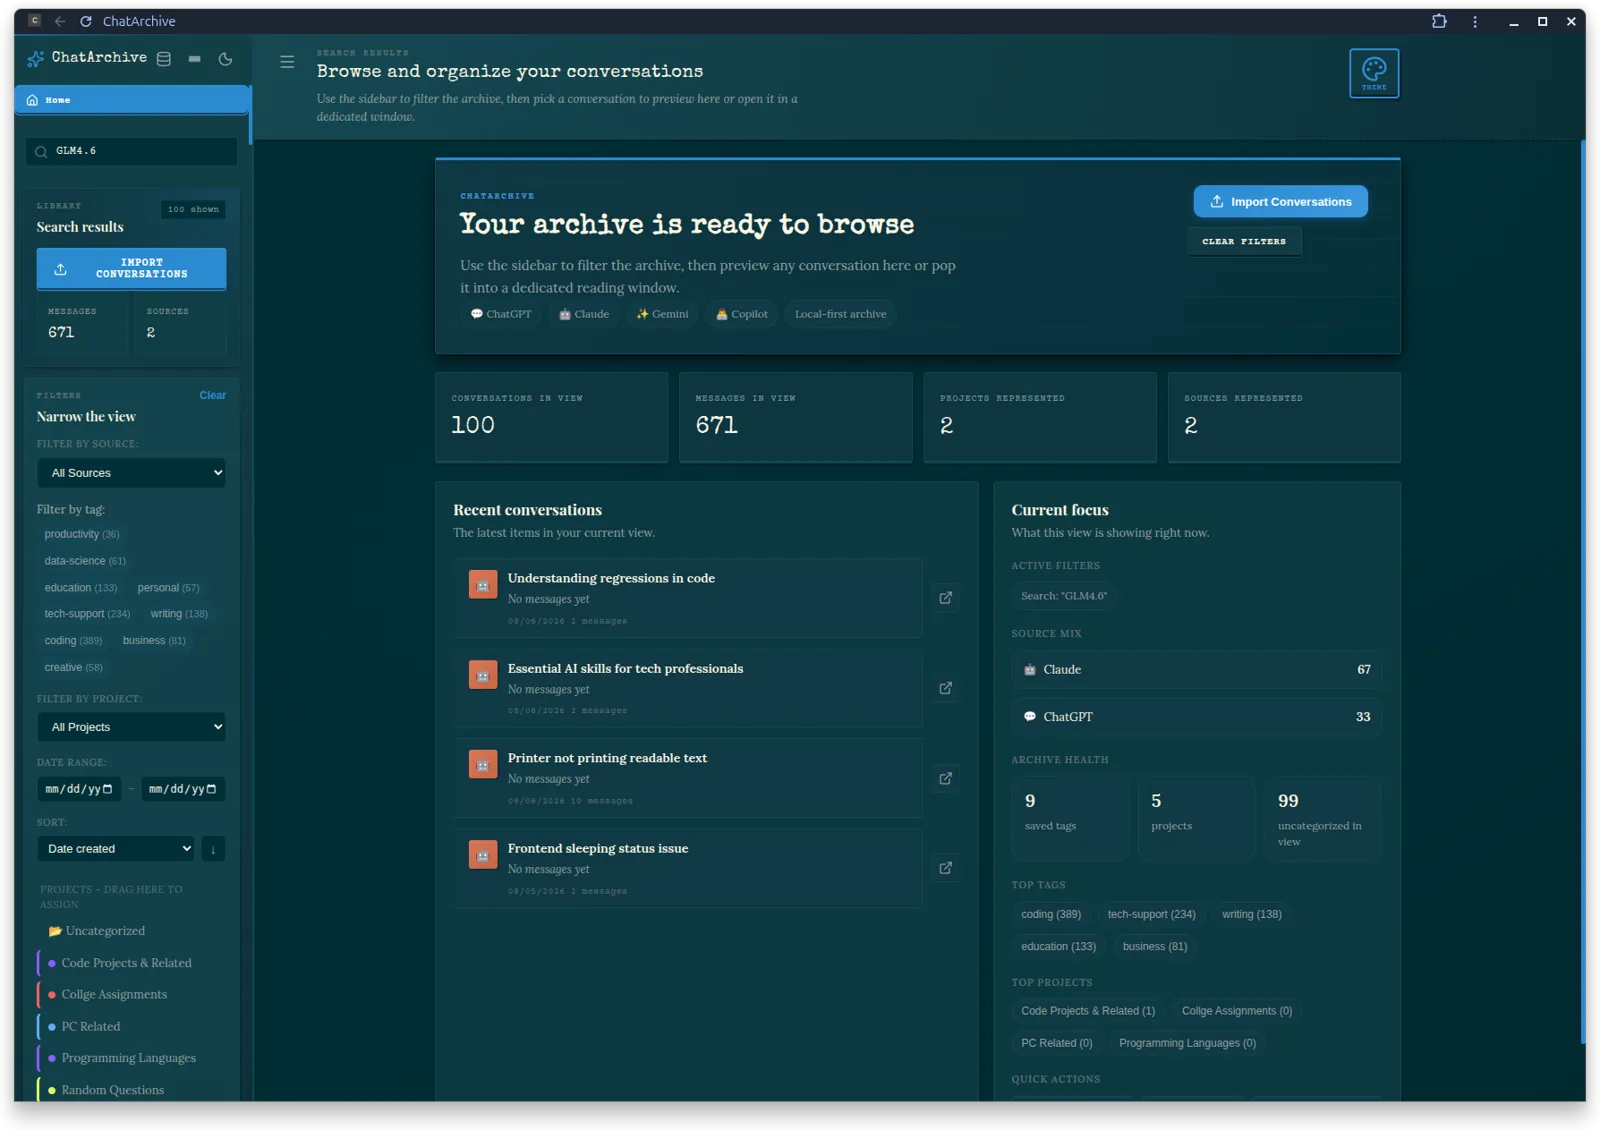
The app uses Supabase PostgreSQL as its database. The frontend talks to FastAPI rather than connecting to Supabase directly, and data endpoints require an application bearer token. In the interface, conversations can be searched, filtered by source, tags, project, and date, and opened with their messages in order. The repository also includes export and analytics views.
Decisions
PostgreSQL instead of a local SQLite fallback. The current backend requires a PostgreSQL connection at startup and uses it for the shared conversation model. That supports PostgreSQL full-text search and a database reachable beyond one machine, but it also means the app needs database configuration and connectivity even when the UI runs locally. Earlier SQLite references in the project are historical, not a supported runtime mode.
Provider-specific parsers feeding one data model. ChatGPT, Claude, Gemini, and Copilot exports do not share one schema. Keeping a parser for each source confines format-specific handling to the import layer; the rest of the app works with the same conversation and message records. A provider format change still requires updating its parser and tests.
Full-text search with a fallback. When the PostgreSQL search migration is present, the search endpoint uses a tsvector query and ranks matches. For a missing search column or a query that cannot produce a useful full-text term, it falls back to ILIKE matching on titles and message content. Search remains available without the indexed path, though it loses full-text relevance ranking.
Result
ChatArchive now has import flows for four providers and one interface for browsing, searching, tagging, and grouping their conversations. Export and analytics views extend that library beyond file storage, while the source-specific parsers keep new import formats out of the browsing code.
Current limits
ChatArchive is still an evolving build. It requires a reachable PostgreSQL database to start, and indexed full-text search depends on its database migration. Most frontend feature logic currently lives in one large App.tsx, which is the clearest candidate for a future split into smaller components.